
Back to paper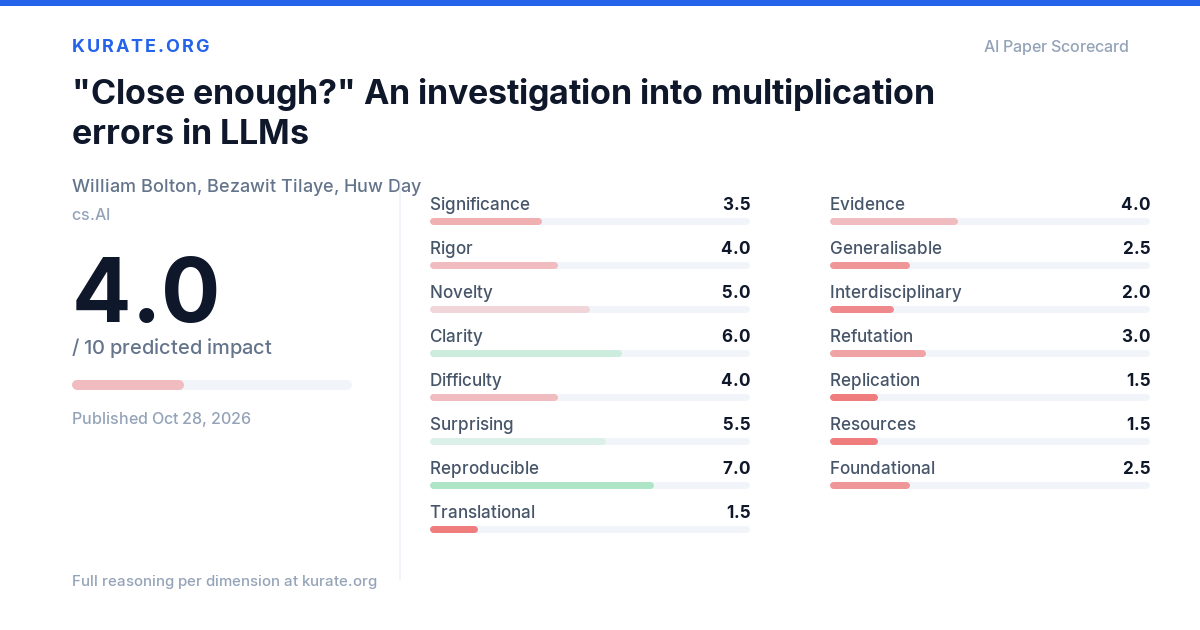 Full reasoning
Oct 28, 2026
cs.AI
Share this scorecard
Every score comes with the model's reasoning on the paper page.
Suggested post
""Close enough?" An investigation into multiplication errors in LLMs" scored 4.0/10 predicted impact on @kurateorg — Reproducible 7.0 · Clarity 6.0 · Surprising 5.5