
Back to paper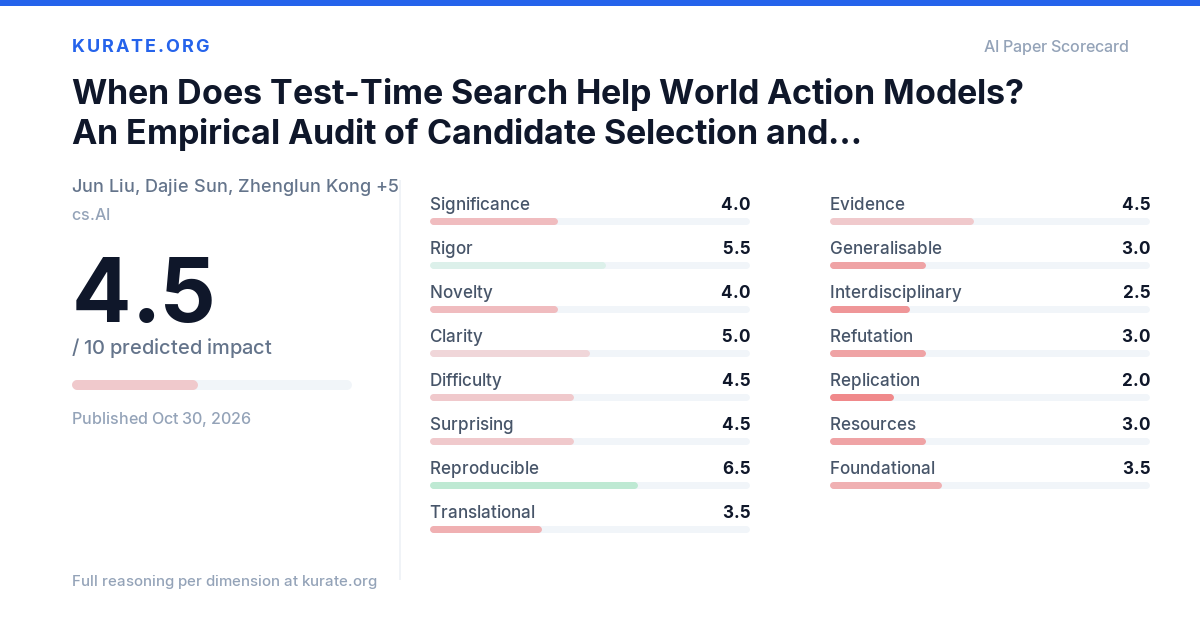 Full reasoning
Oct 30, 2026
cs.AI
Share this scorecard
Every score comes with the model's reasoning on the paper page.
Suggested post
"When Does Test-Time Search Help World Action Models? An Empirical Audit of Candidate Selection and Simulator Integrity" scored 4.5/10 predicted impact on @kurateorg — Reproducible 6.5 · Rigor 5.5 · Clarity 5.0