
Back to paper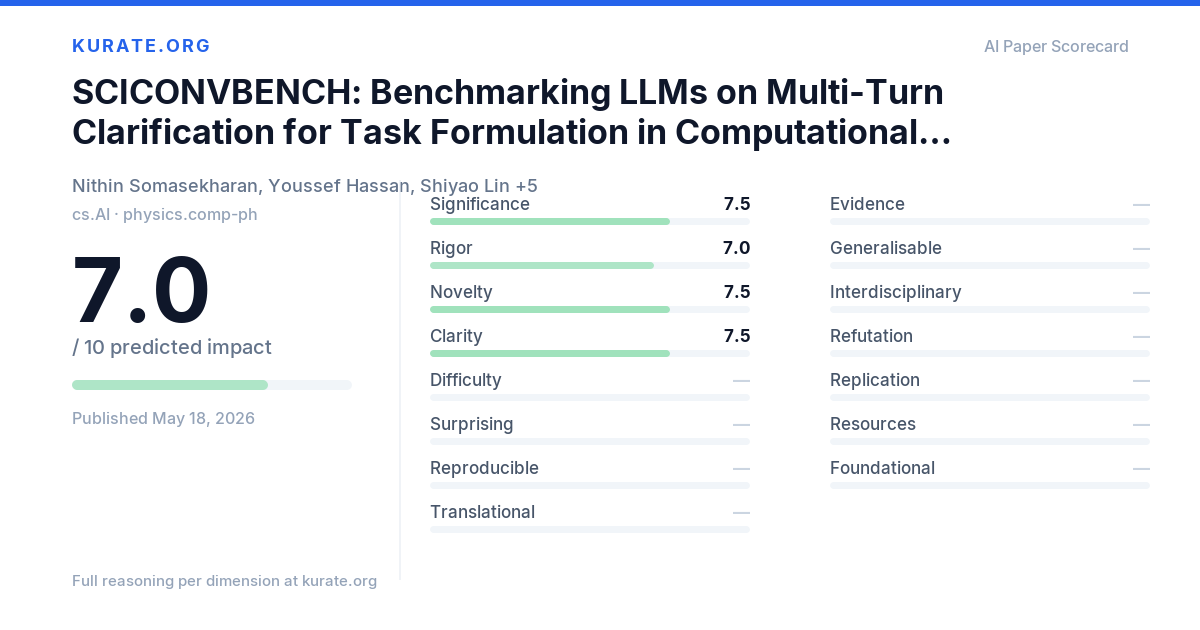 Full reasoning
May 18, 2026
cs.AI · physics.comp-ph
Share this scorecard
Every score comes with the model's reasoning on the paper page.
Suggested post
"SCICONVBENCH: Benchmarking LLMs on Multi-Turn Clarification for Task Formulation in Computational Science" scored 7.0/10 predicted impact on @kurateorg — Significance 7.5 · Novelty 7.5 · Clarity 7.5