
Back to paper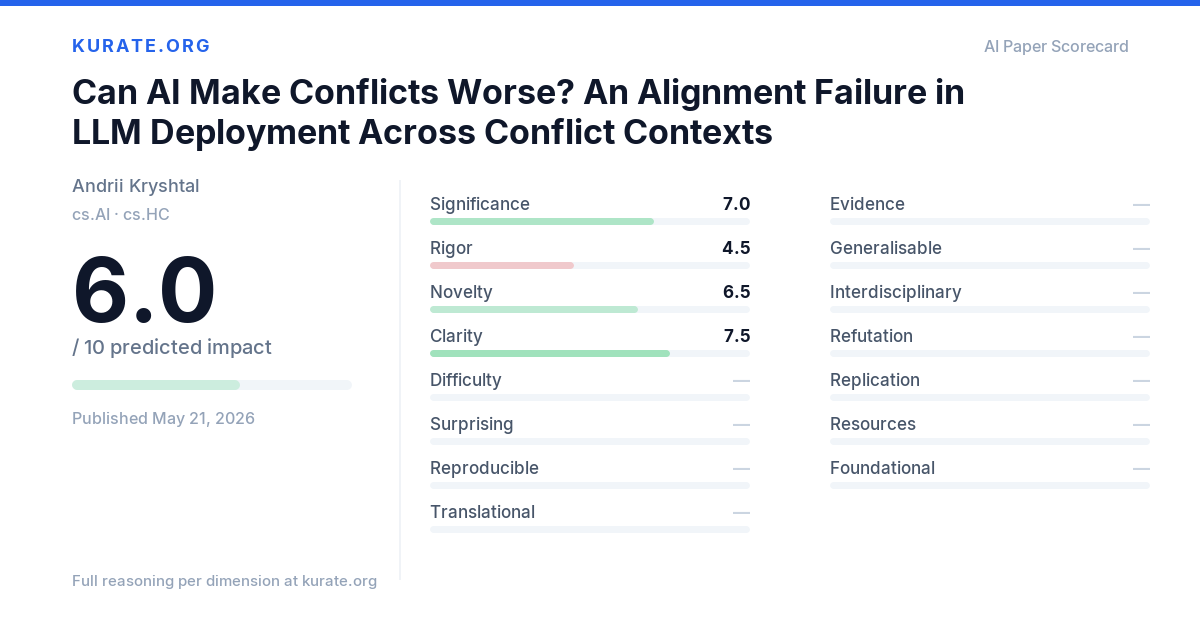 Full reasoning
May 21, 2026
cs.AI · cs.HC
Share this scorecard
Every score comes with the model's reasoning on the paper page.
Suggested post
"Can AI Make Conflicts Worse? An Alignment Failure in LLM Deployment Across Conflict Contexts" scored 6.0/10 predicted impact on @kurateorg — Clarity 7.5 · Significance 7.0 · Novelty 6.5